Overview
 faisalmumtaz89/Lumen
8
Lumen, the inference engine for your own GPU.
Lumen downloads a model and runs it on your own GPU, from the command line or an OpenAI- and Anthropic-compatible server, and paints images too. Written from scratch in Rust, native on Apple Silicon and NVIDIA.
curl -fsSL https://servelumen.com/install.sh | bash
Needs the NVIDIA driver. Run every command on this page in a terminal.
Needs the NVIDIA driver on Windows. In an admin PowerShell, run wsl --install -d Ubuntu-24.04 and restart (again if Ubuntu isn't installed yet), then run every command on this page in Ubuntu 24.04.
Quick start
Two paths, start to serving.
-
Install
Needs an NVIDIA GPU and its driver. One command installs everything else.
Installcurl -fsSL https://servelumen.com/install.sh | bash -
Run
In a new terminal, name the model and a prompt, and Lumen prints the answer. The first run downloads Qwen3.8 27B (16 GB) and converts it, keeping about 33 GB of disk, then compiles its GPU kernels in about a minute.
Runlumen run qwen3.8-27b "Write a haiku about light" -
Serve
Start the server. It downloads a model it does not have yet, then answers on localhost:8000, on this machine only. It has no login, so share it with --host 0.0.0.0 only on a network you trust.
Servelumen-server qwen3.8-27b -
Ask
In a second terminal, send a chat request. OpenAI Chat Completions clients connect at http://localhost:8000/v1 and Anthropic Messages clients at http://localhost:8000, with the model qwen3.8-27b and any API key.
Askcurl localhost:8000/v1/chat/completions -H 'content-type: application/json' -d '{"model":"qwen3.8-27b","messages":[{"role":"user","content":"Write a haiku about light"}]}'
-
Install
The same install.
Installcurl -fsSL https://servelumen.com/install.sh | bash -
Picture
In a new terminal, describe a picture, and Lumen saves it as a PNG in this folder. Stop the text server first if it is running. It needs a GPU with at least 21 GiB of memory. The first run downloads and converts Qwen-Image-2.1, keeping 30.8 GiB and using up to 78 GiB of disk while it converts.
Picturelumen image "A red apple on a wooden table" -
Serve
Start the image server. It serves pictures only, so stop the text server first if it is running.
Servelumen-server qwen-image -
Generate
In a second terminal, send a prompt to the OpenAI-compatible images endpoint and save the picture.
Generatecurl -fsS localhost:8000/v1/images/generations -H 'content-type: application/json' -H 'accept: image/png' -d '{"prompt":"A red apple on a wooden table","size":"1024x1024"}' -o apple.png
Why Lumen
Built to owe nothing to anyone's stack.
-
Nothing to build
Lumen itself needs no Python and no config files, and you compile nothing. Lumen downloads and converts a model the first time you use it, and compiles its GPU kernels on the first run.
-
Truly native
Written from scratch in Rust with its own GPU code for Apple Silicon and NVIDIA, not a wrapper around someone else's engine.
-
Works with your tools
The built-in server speaks the OpenAI and Anthropic APIs, so anything that talks to them talks to Lumen.
Benchmarks
Kernel against kernel, nothing else.
Decode throughput on the same model, batch 1, no speculative decoding, every engine measured on the same card in one sitting. Untagged rows run the same weight bytes, a row tagged with a format runs a different quantization of the same model.
Method: one stream, greedy decode, no speculative decoding, every engine back to back on the same card, five runs after a warmup, speed is decode tokens per second. CUDA cells, under Linux: Lumen at defaults (v0.34.0 on the RTX 5090, v0.31.0 on A100 and H100), 1,024-token prompt, 128 generated tokens (RTX 5090 with its clock pinned). The NVFP4 cell runs one NVIDIA ModelOpt checkpoint in every engine, N/A marks an engine that cannot load it. Rows without a tag run the same weight bytes, a tagged row runs a different quantization of the same model.
Images
Dream it. Render it.
Qwen-Image-2.1, running natively in Lumen. Crisp 2.7K widescreen, and up to 4K if you dare.
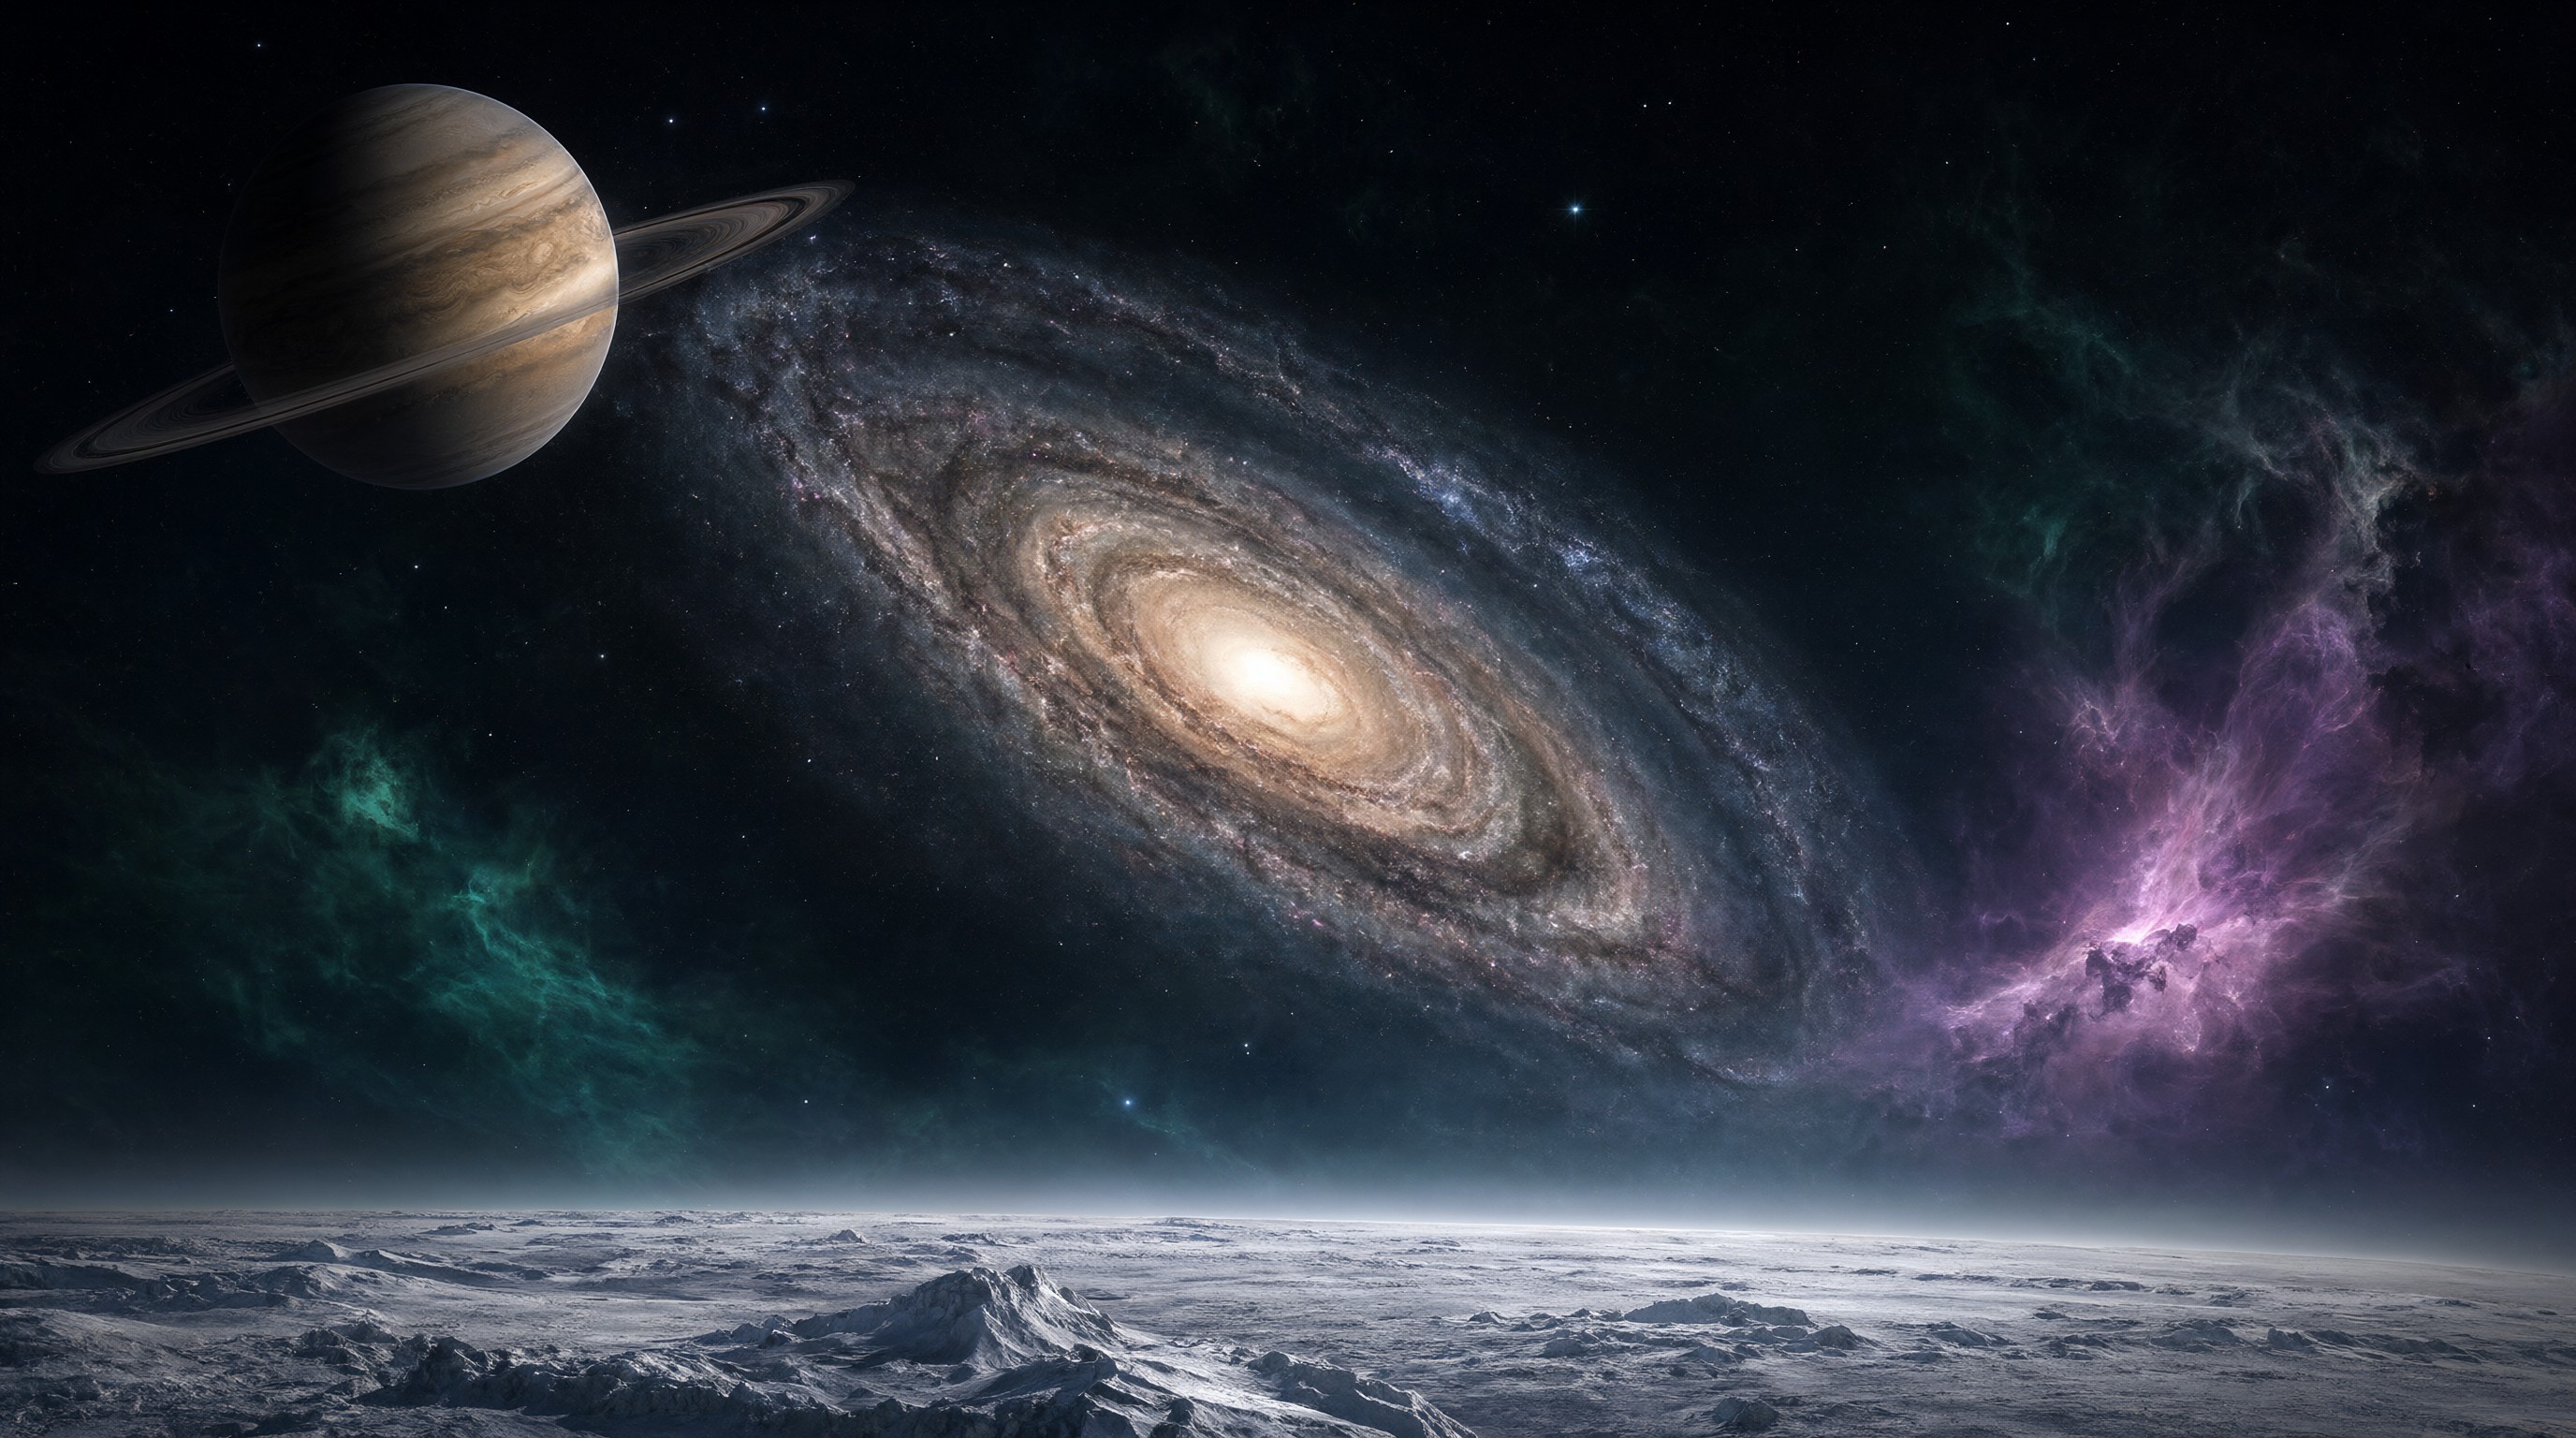
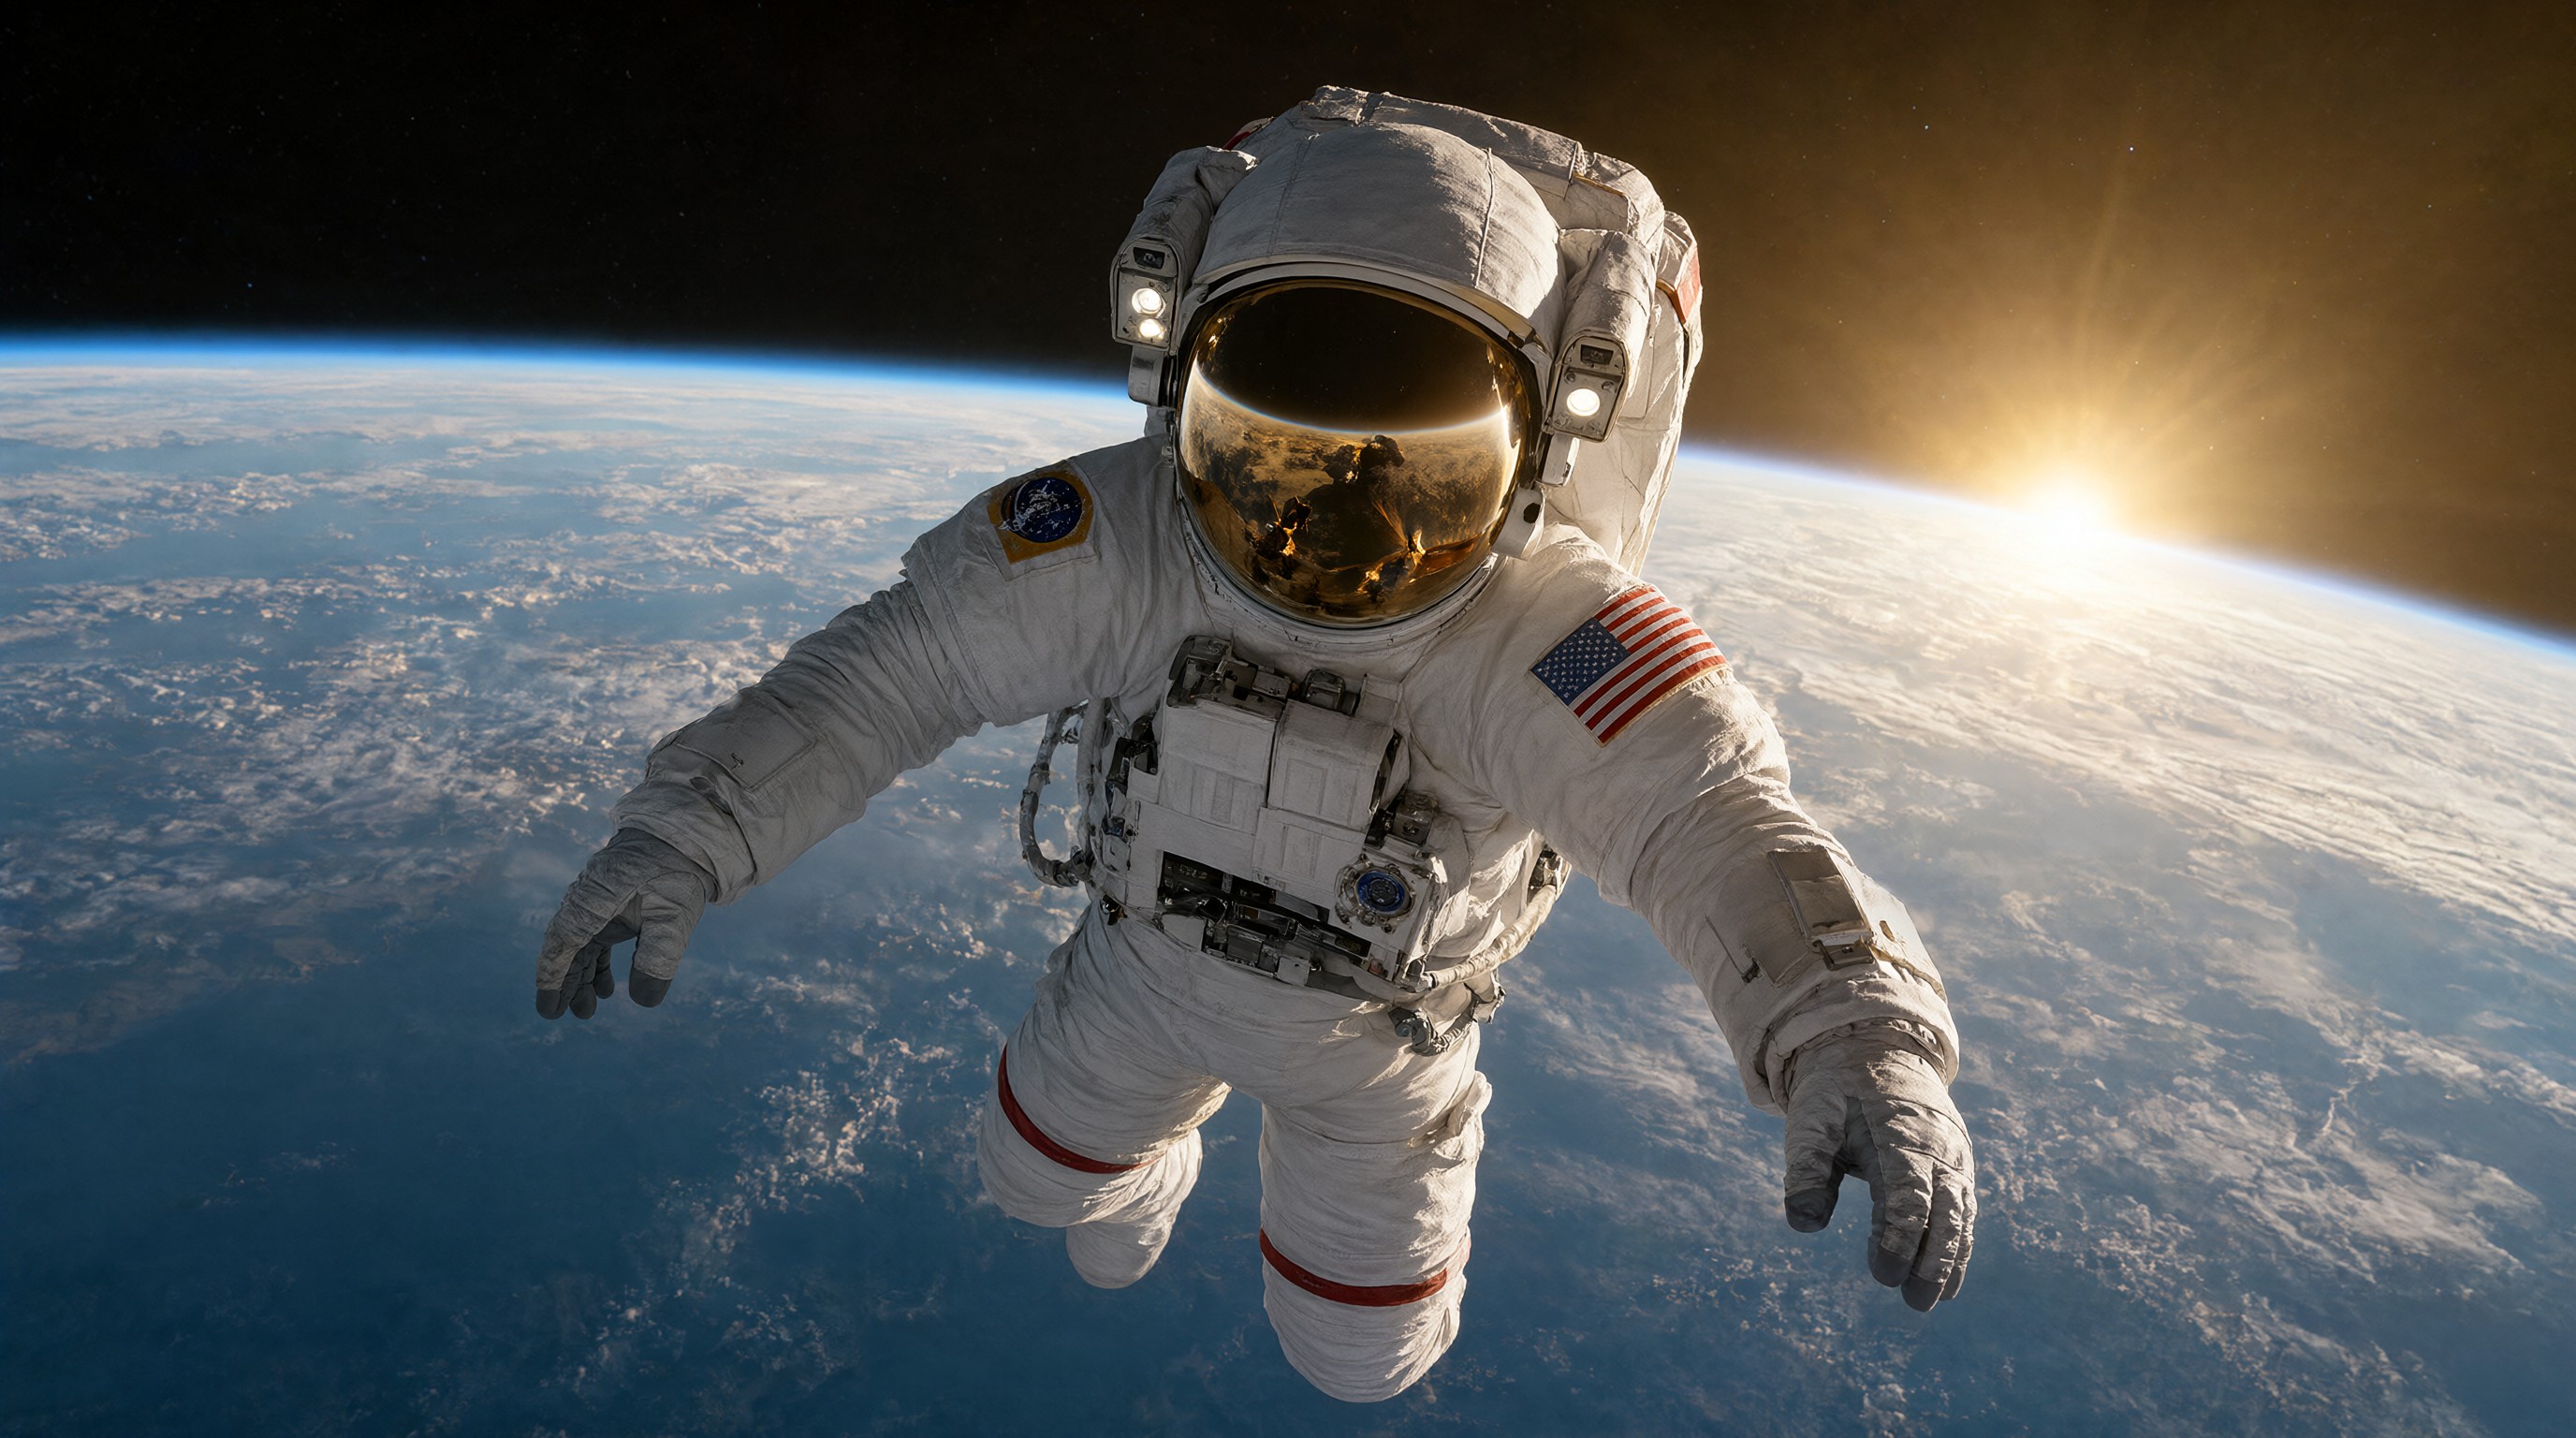
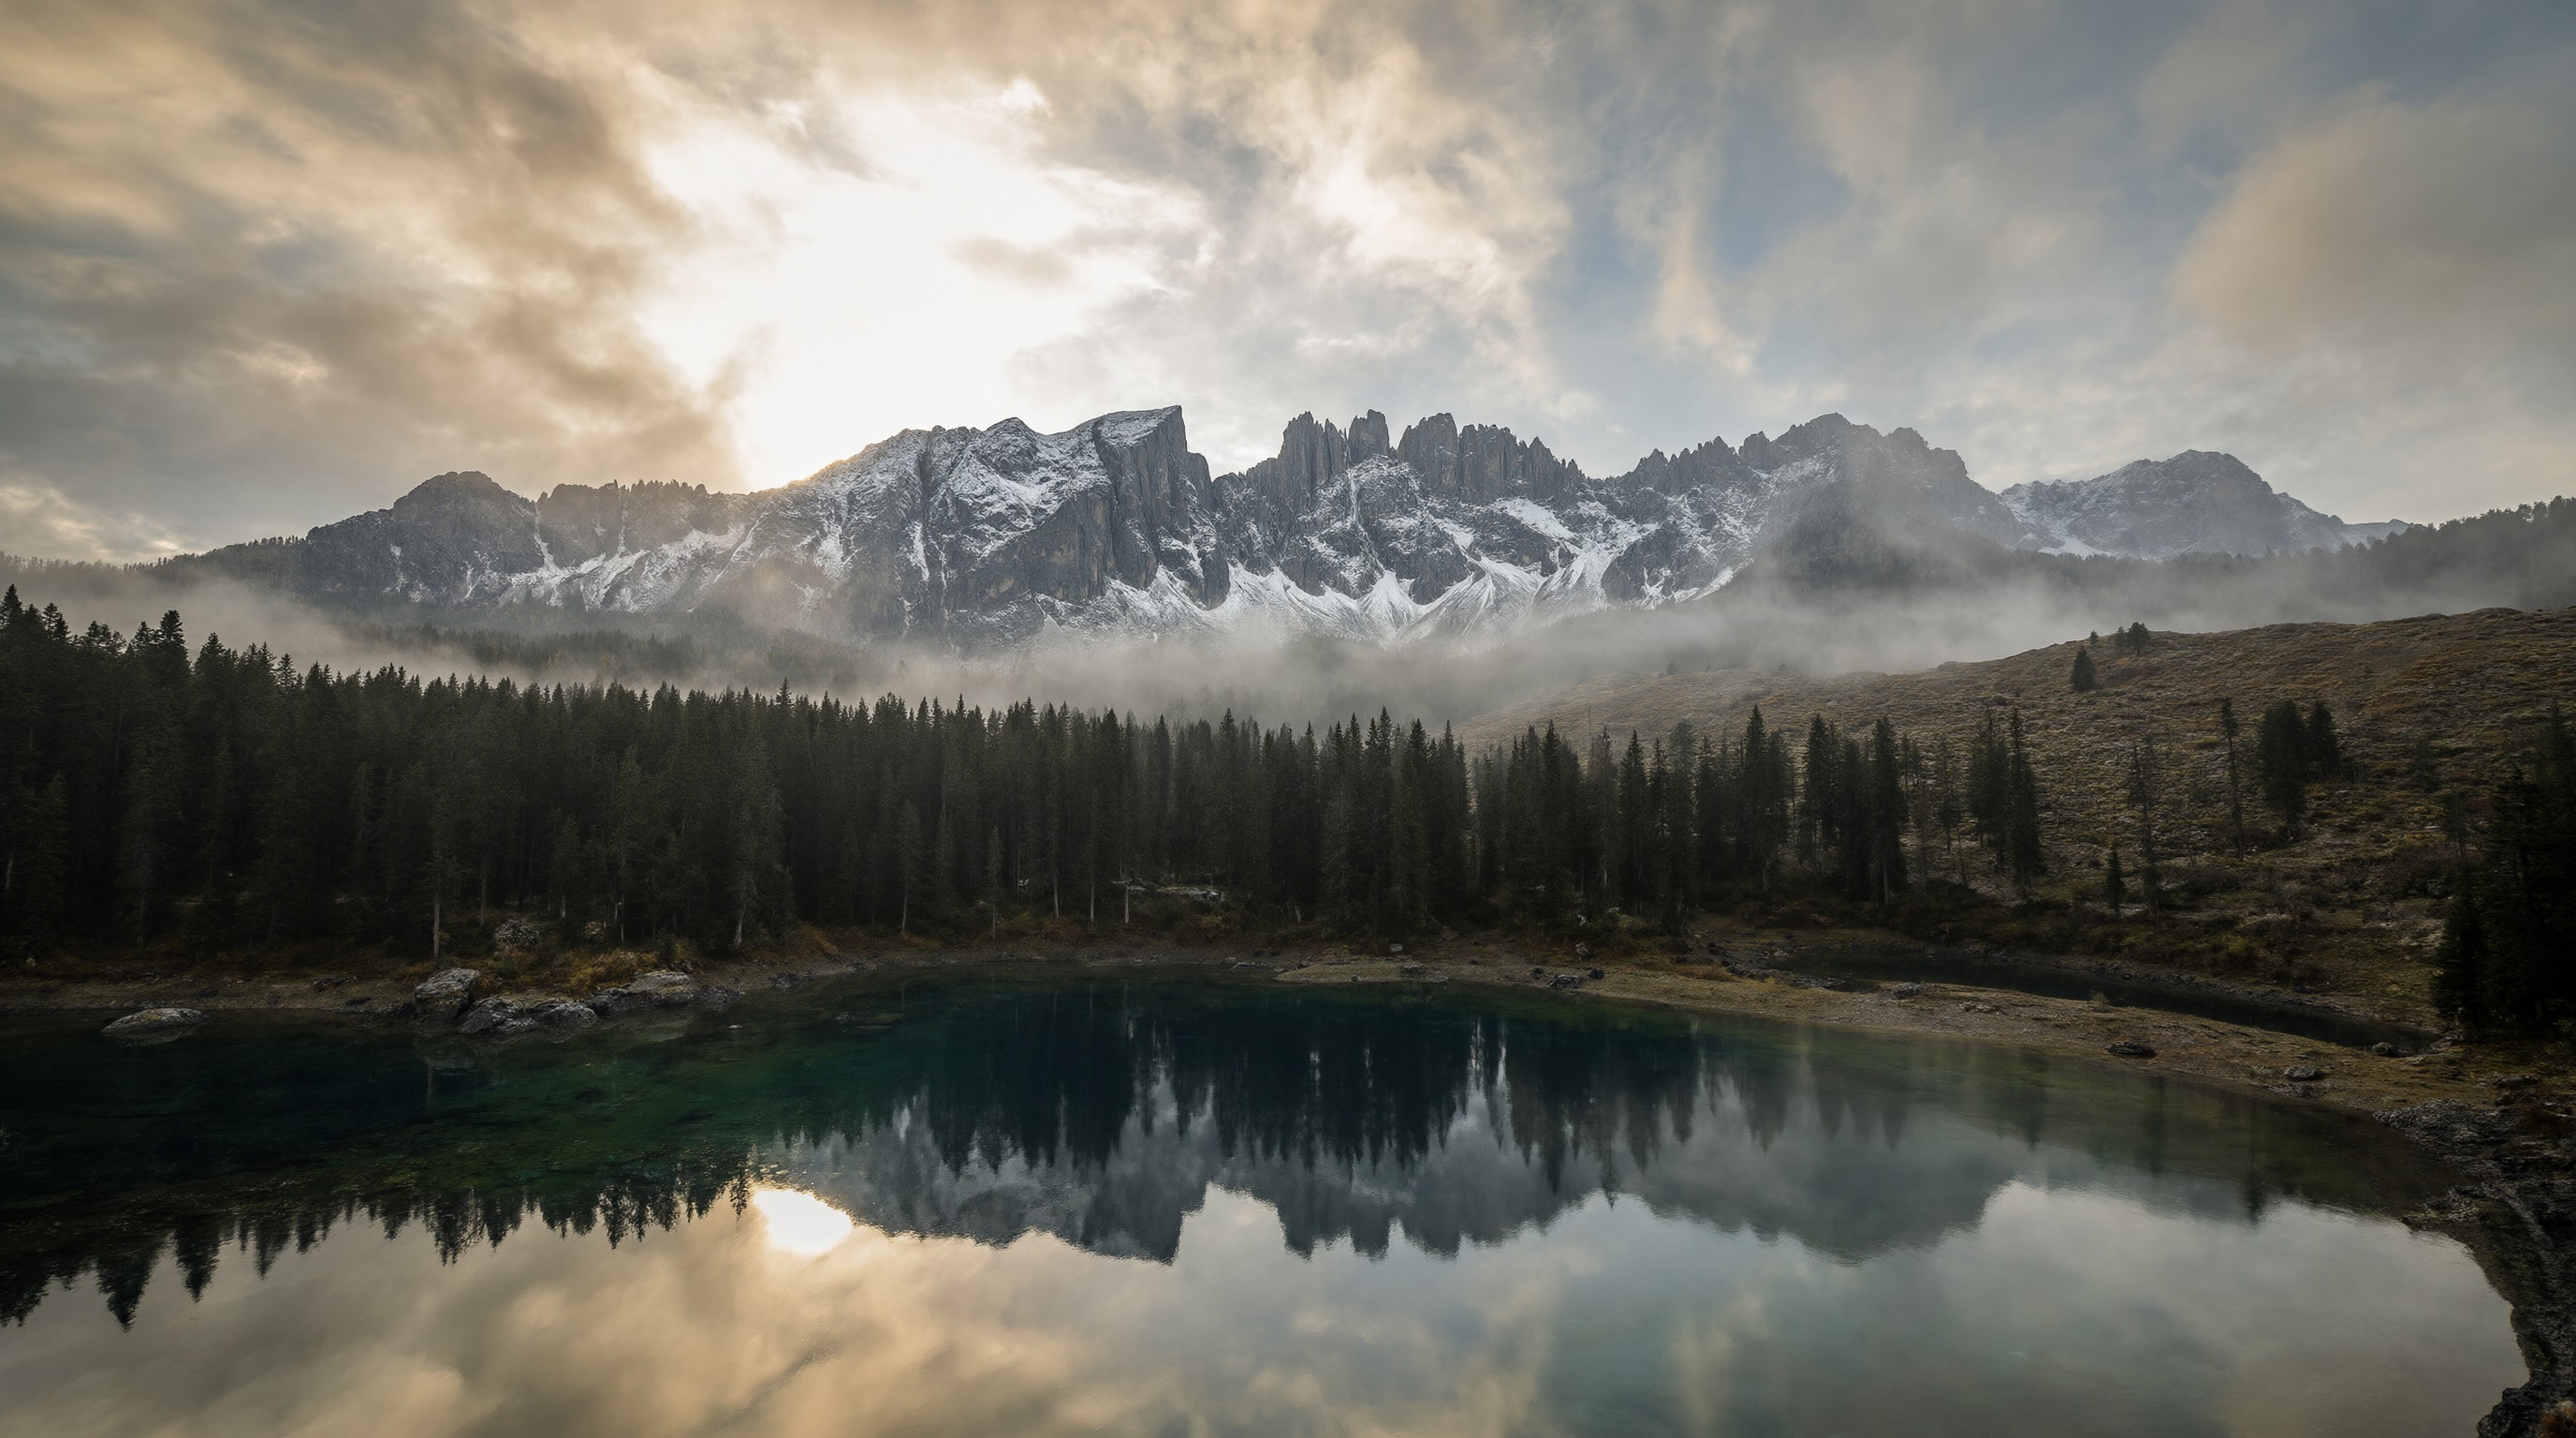
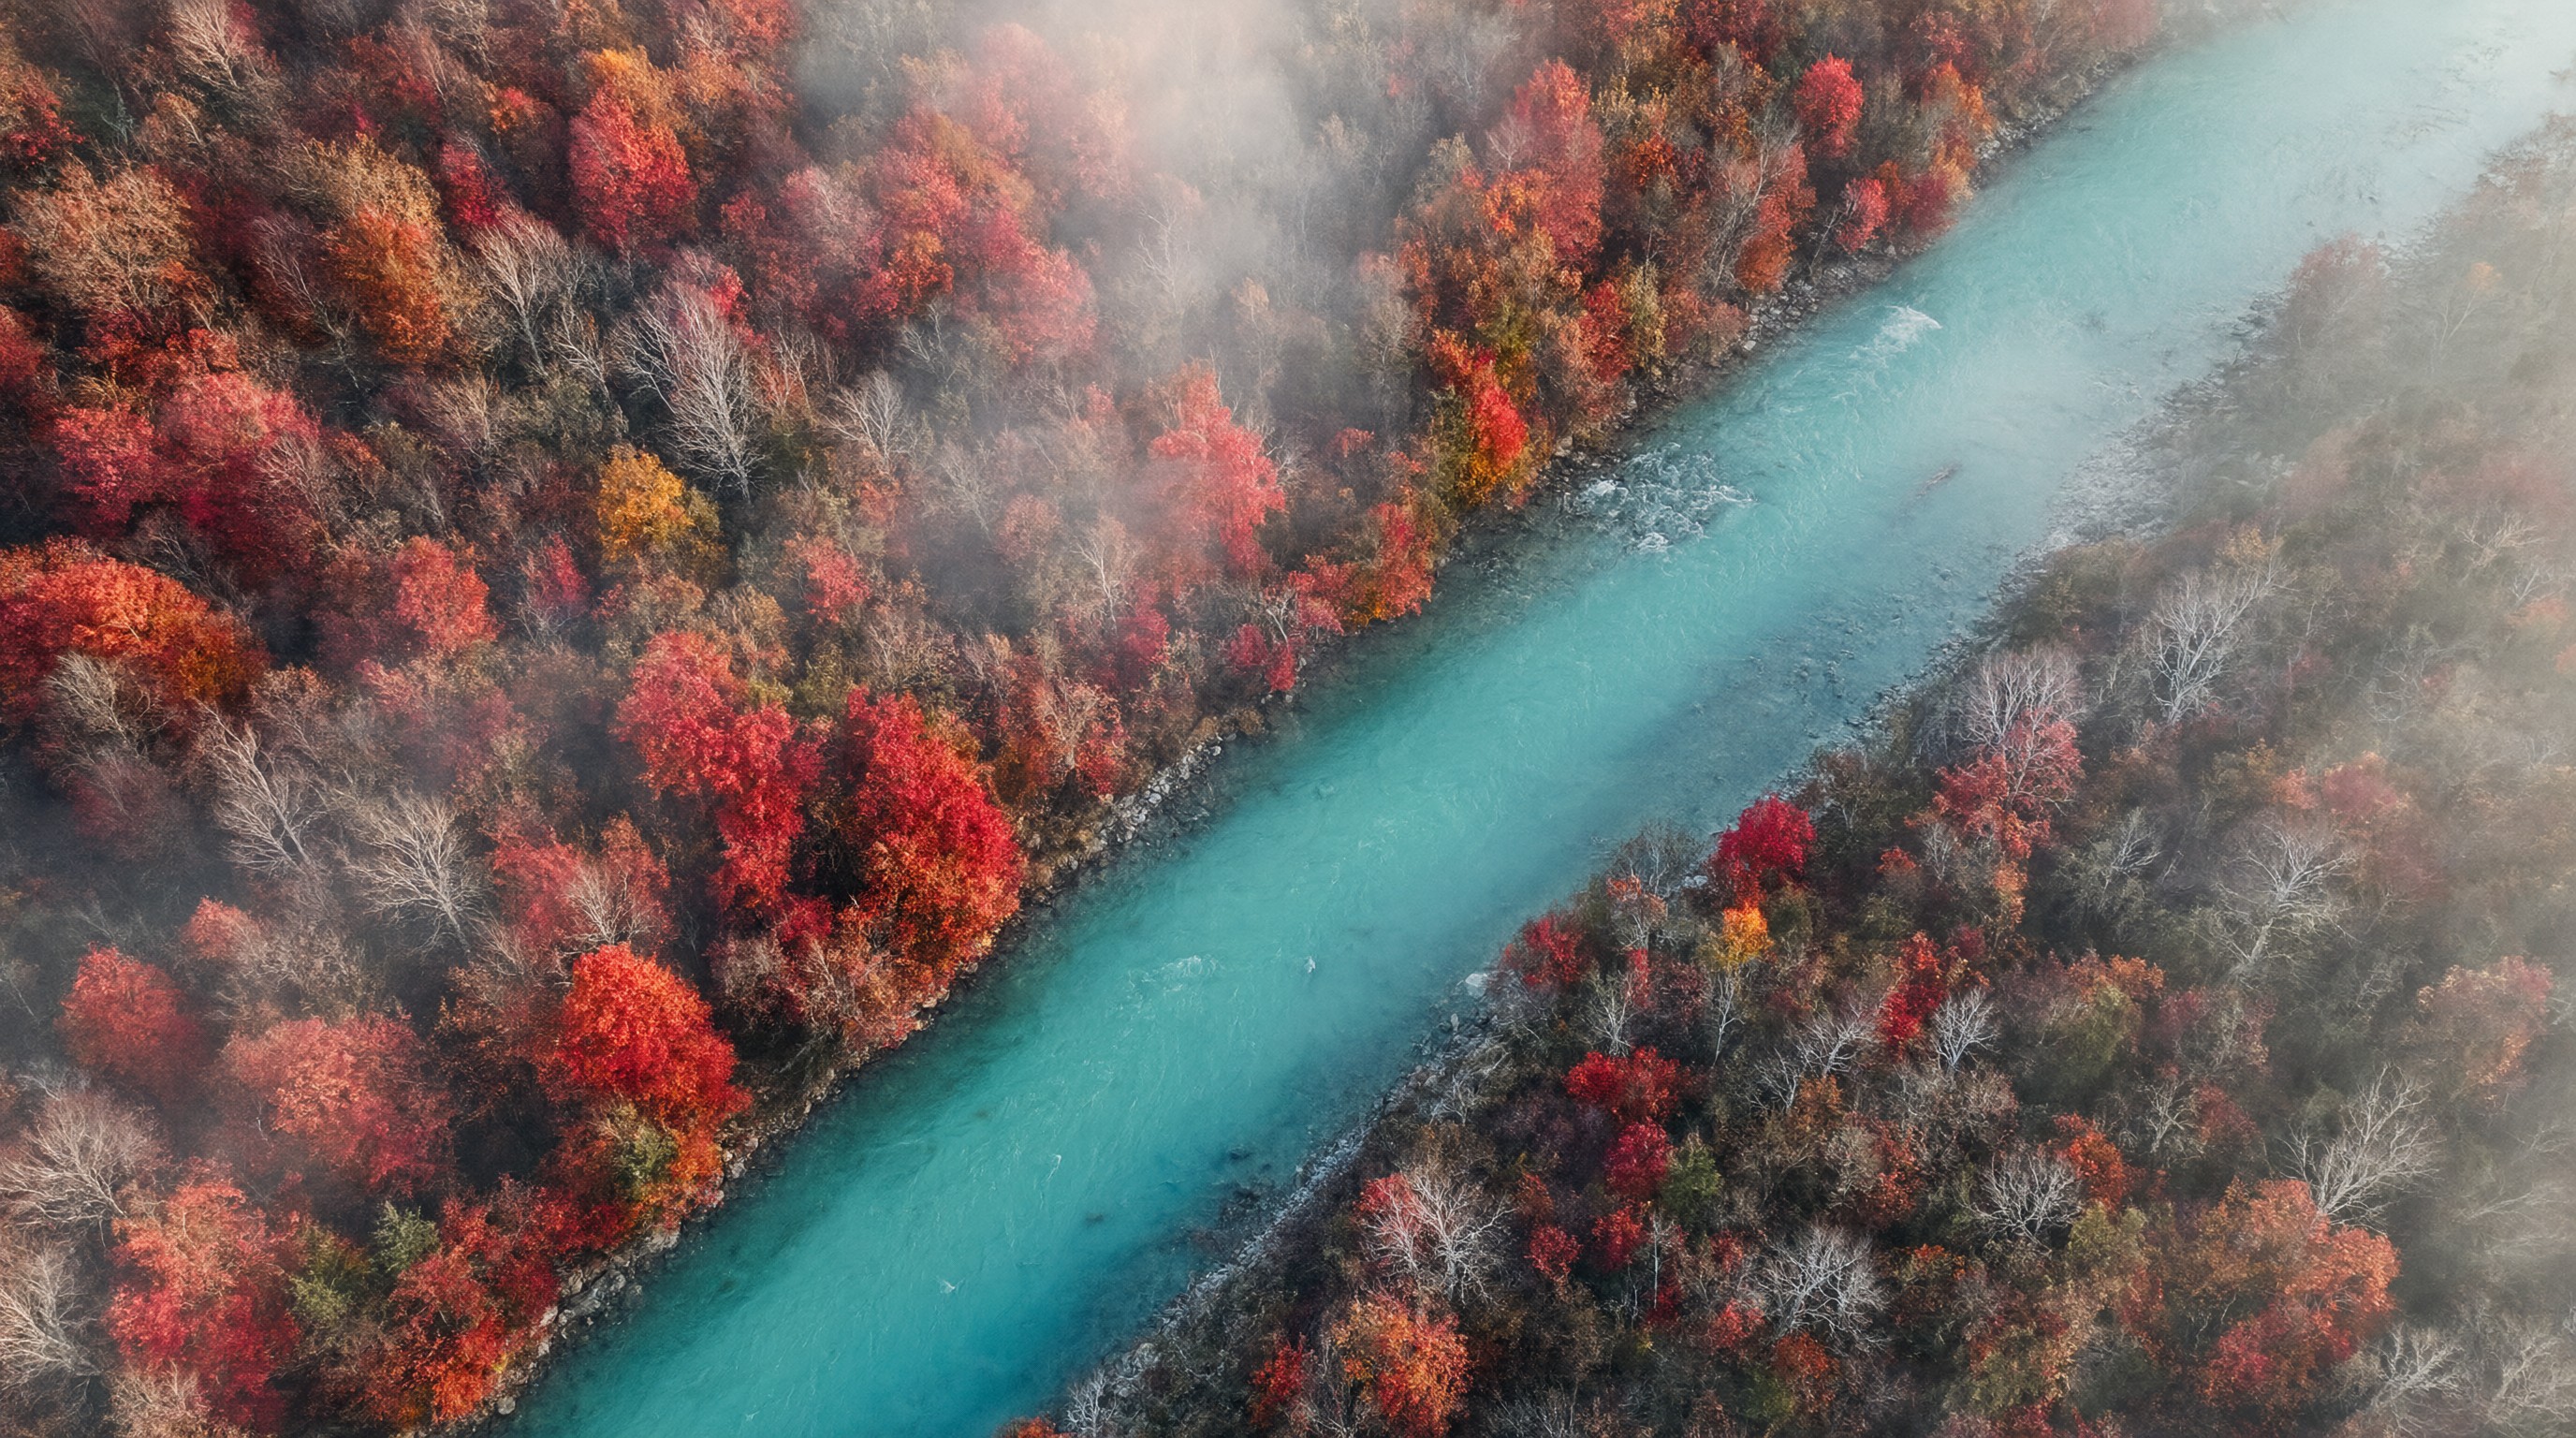
Seconds per 1024×1024 image · 40 steps · RTX 5090 · shorter is fasterbf16
- lumen12.9 s
- sglang13.9 s
- vllm17.0 s
Method: Qwen-Image-2.1 in bf16 at 1024×1024, 40 steps, guidance off, same prompt and seed for every engine. All engines ran back to back on one RTX 5090 under Linux, 20 timed images each after warm-ups, with the run order reversed halfway. Each engine used its recommended single-GPU setup. Gallery images are 2752×1536, the model's largest 16:9 size, at 40 steps, rendered by Lumen v0.33.0. Text and images come from the same lumen binary, with no Python and no extra runtime.
Platform
One CUDA build, every modern NVIDIA.
-
Compute capability 7.5+
Turing and newer on x86-64 Linux: T4, A100, H100, RTX 20-, 30-, 40- and 50-series. One release binary covers all of them. On Windows 11 it runs under WSL on GeForce cards, verified on an RTX 5090. On Turing the 9B at Q8_0 and Q4_0 is verified, and Q4_K_M, Q5_K_M, INT4 and image generation need Ampere or newer.
-
Driver plus CUDA libraries
Kernels JIT-compile at runtime via NVRTC and are cached after the first run. It needs only the NVIDIA driver. The installer adds everything else.
-
Fits your card
-
Bring your quantization
BF16, Q8_0 and Q4_0 on every model, Q4_K_M and Q5_K_M served natively by their own kernels, NVFP4 and FP8 checkpoints served as stored, and INT4 checkpoints imported from Hugging Face bit for bit.
- BF16
- Q8_0
- Q4_0
- Q4_K_M
- Q5_K_M
- NVFP4
- FP8
- INT4
Server
An API your tools already speak.
Boot lumen-server and point any OpenAI or Anthropic client at port 8000.
POST /v1/chat/completions   OpenAI · SSE
POST /v1/completions        OpenAI
POST /v1/messages           Anthropic · SSE
POST /v1/images/generations OpenAI · images
GET  /v1/models
-
Streaming and tool calls
SSE streaming on both wire formats, with template-driven tool-call parsing that survives split markers mid-stream.
-
Extended thinking
A per-request reasoning toggle with its own token budget, separate from max_tokens, so a long trace never starves the answer.
-
Reproducible on demand
Kernels are deterministic at a fixed seed. Pass seed, or temperature 0, and the same request returns the same tokens.
Format
LBC, our own format.
Models run from .lbc, Lumen's Layer-Blob Container, built for how inference actually reads weights.
-
Self-contained
Weights, hyperparameters, and the full tokenizer (token table, merges, special tokens, chat template) in one file. No sidecar files to lose.
-
One blob per layer
Each layer is a contiguous blob at a 128 KiB-aligned offset, so weights memory-map zero-copy and load GPU-resident or stream layer by layer.
-
Per-tensor quantization
A file-level scheme with per-tensor overrides, so one file can mix BF16, Q8_0, Q4_0, Q4_1 and the K-quants. Conversion can keep every tensor in its source format, so the file streams the same weight bytes the source provides.
-
Reads other engines' checkpoints
lumen convert --from-hf imports compressed-tensors INT4 checkpoints with values preserved exactly, so Lumen runs the same file vLLM and SGLang serve.
-
Versioned, checksummed
Header and tokenizer sections carry CRC32s. Readers accept versions up to 5 and reject newer files outright rather than misread them.
Model registry
Name a model. Lumen does the rest.
-
qwen3.5-9b
9BFast and light. The best place to start.
-
qwen3.5-moe
35B · MoEMixture-of-experts: big-model answers, small-model speed.
-
qwen3.8-27b
27BThe newest generation, supported from day zero.
-
Qwen-Image-2.1
Text → imageFrom a sentence to a finished picture, with the same lumen binary.